SEOmator's September 2026 AI crawler report: search-purpose crawling reached 10.6% of AI-bot requests worldwide, four times its January share (2.6%) and nearly double July's (5.6%). In the same months GPTBot, OpenAI's training crawler, fell from 12.6% of AI-bot traffic to 6.2%, while PerplexityBot grew more than sixfold after July, to 2.2%. The global figures are Cloudflare Radar calendar months; our own panel's figures run through July 2026.
Key takeaways from the September 2026 AI crawler report:
- Search-purpose crawling: 2.6% (January) → 5.6% (July) → 10.6% (September 2026) of AI-bot requests on Cloudflare Radar. Training eased from its 52.6% June peak to 44.0%, back to January's level.
- GPTBot: 12.6% (January) → 6.2% (September) of AI-bot traffic. OAI-SearchBot more than doubled, 1.7% → 3.6%. In January about one in five of OpenAI's AI-bot requests came from its search or user agents; in September it was 45%.
- PerplexityBot: 0.3% (July) → 2.2% (September) of AI-bot traffic, while Perplexity's crawl-to-refer ratio went from 296:1 to 2,373:1. It crawls more and sends less back.
- ClaudeBot settled at 12.0% in September, level with January's 11.8%. Meta-ExternalAgent (13.1%) has held the #2 spot behind Googlebot since August.
- 38.1% of crawler requests were answered with a 4xx in September 2026, the highest month of the year (33.1% in January). Deliberate 403s alone were 23.8%.
- On Radar's October 5, 2026 scan of 4,261 robots.txt files, GPTBot is named in 703 and disallowed in 546. Search agents get allowed about as often as they get blocked: OAI-SearchBot is allowed in 316 files and disallowed in 279.
Who operated the most bot traffic in September 2026?
Google still operates more bot traffic than anyone else, and it has stopped losing ground. Its share of global bot traffic on Cloudflare Radar slid from 37.3% in January 2026 to a low of 26.6% in August, then ticked back up to 27.3% in September. Meta is a firm #2 at 17.5%. The two labs that dominate AI headlines went the other way: Anthropic fell from 12.7% in June to 7.3%, and OpenAI from 9.2% in January to 4.7%, half its starting share.
| Operator | Panel, Jan | Panel, Jul* | Radar, Jan | Radar, Jul | Radar, Aug | Radar, Sep |
|---|
| Google | 42.6% | 30.8% | 37.3% | 27.1% | 26.6% | 27.3% |
| Meta | 13.5% | 12.2% | 15.1% | 14.6% | 18.6% | 17.5% |
| Anthropic | 14.1% (Jun) | 12.7% | 12.7% (Jun) | 11.0% | 8.5% | 7.3% |
| OpenAI | 9.7% | 7.4% | 9.2% | 6.5% | 5.7% | 4.7% |
| Microsoft | 7.2% | 6.2% | 6.5% | 5.5% | 5.1% | 5.5% |
| Amazon | 3.2% | 4.3% | 3.6% | 4.7% | 4.8% | 4.3% |
* Panel figures for July 2026 cover July 1-21 (partial month); the panel has not been re-derived for August or September. Radar: share of global bot traffic by operator, calendar months of 2026. Anthropic enters both series in June 2026, when Radar's bot taxonomy expanded (our panel mirrors that taxonomy), so its first column shows June.
The mid-table is where the year's real change sits. Apple tripled its share, from 1.5% of global bot traffic in January to 4.5% in September, and Applebot is now the fourth-largest AI bot on Radar. Ahrefs' crawler, an SEO tool rather than an AI lab, runs at 4.4%, level with Amazon. The crawl economy keeps fragmenting: no single operator picked up the ten points Google gave away this year.
On the sites we track, Google's operator share fell from 42.6% in January to 30.8% in July (Jul 1-21), the same slope from a higher start; the likeliest reason is our B2B tilt, since software companies live and die by Google Search. The scale behind all of these shares keeps growing: according to Cloudflare Radar data shared by CEO Matthew Prince on June 3, 2026, bots now generate 57.5% of HTML web traffic.
📊By the Numbers: OpenAI's share of global bot traffic halved in 2026, from 9.2% in January to 4.7% in September on Cloudflare Radar. Meta (17.5%) now operates more than three times as much bot traffic as OpenAI.
Drill from operators down to individual bots on our panel and the diversification sharpens. Googlebot alone accounted for about 21% of all bot hits on our panel in January 2026; by July (Jul 1-21) it was down to about 12.5%. In June and July the #2 individual bot we saw wasn't a search crawler at all. It was Claude-User, the agent that fetches a page because a human asked Claude a question, at roughly 10-11% of bot hits. Where that agent traffic originates varies widely by geography; we mapped that in our breakdown of AI bot traffic by country.
Search bots climb, GPTBot halves: what moved in September?
September's headline is a change of job, not a change of size. OpenAI's training crawler is shrinking while its search crawler grows. GPTBot fell from 12.6% of global AI-bot traffic in January 2026 to 6.2% in September, a little under half. OAI-SearchBot, which fetches pages for ChatGPT's search answers, went from 1.7% to 3.6%. Add ChatGPT-User, the live fetcher, and OpenAI's mix flipped: in January 19% of its AI-bot requests came from search or user agents, and in September 45% did.
| AI bot user agent | Jan | Jun | Jul | Aug | Sep |
|---|
| Googlebot | 38.5% | 25.2% | 24.5% | 23.0% | 24.5% |
| Meta-ExternalAgent | 10.9% | 10.2% | 12.5% | 14.1% | 13.1% |
| ClaudeBot | 11.8% | 19.8% | 16.5% | 11.9% | 12.0% |
| Applebot | 2.5% | 6.0% | 6.5% | 6.6% | 8.5% |
| Bingbot | 9.9% | 7.8% | 8.9% | 7.5% | 7.6% |
| Amazonbot | 4.8% | 5.4% | 6.0% | 8.1% | 6.2% |
| GPTBot | 12.6% | 9.4% | 9.7% | 8.3% | 6.2% |
| OAI-SearchBot | 1.7% | 1.5% | 1.6% | 3.1% | 3.6% |
| Bytespider | 3.5% | 7.6% | 5.3% | 3.7% | 3.3% |
| Claude-SearchBot | 0.7% | 3.3% | 3.5% | 3.7% | 2.7% |
| PerplexityBot | 0.2% | 0.2% | 0.3% | 1.1% | 2.2% |
| ChatGPT-User | 1.3% | 1.3% | 1.3% | 2.5% | 1.5% |
Cloudflare Radar, share of global AI-bot traffic by user agent, calendar months of 2026. The July edition's August column covered Aug 1-28; these are full-month values.
PerplexityBot is the fastest riser on the board. It sat at 0.2% of AI-bot traffic from January to June, reached 0.3% in July, then 1.1% in August and 2.2% in September, more than six times its July share in two months. Its referrals did not keep up, which the crawl-to-refer section below puts in numbers.
ClaudeBot's summer spike is now fully over. It doubled between May and June (9.9% to 19.8%), cooled to 16.5% in July, and has sat at 11.9-12.0% since August, January's level. That was a bulk re-crawl cycle, not a lasting change in appetite. Claude-SearchBot, Anthropic's citation crawler, dipped from 3.7% to 2.7% in September.
📈Trend Watch: Googlebot held 38.5% of global AI-bot traffic in January 2026 and 24.5% in September. Over the same months Applebot went from 2.5% to 8.5% and PerplexityBot from 0.2% to 2.2%. The crawl economy is steadily diversifying away from one dominant bot.
The long tail filled in fast, too. Bravebot, Brave's AI search crawler, and xAI's Grok agent were near zero through August and took about 0.8% of AI-bot traffic each in September. ShapBot (1.5%), YouBot (1.4%), MistralAI-User (0.8%), cohere-ai (0.8%) and CCBot (0.8%) all grew several times over since July. Most of these newcomers are search or assistant agents, which is the same tilt the purpose data below shows.
⚠️Common Mistake: GPTBot and OAI-SearchBot are different bots with different jobs, and so are ClaudeBot and Claude-SearchBot. The first of each pair gathers training data; the second fetches pages to cite in answers. A robots.txt rule that blocks both costs you citations, not just training exposure.
What are AI crawlers doing with your content?
Less training, more searching. Training-purpose crawling peaked at 52.6% of global AI-bot requests in June 2026 and fell to 44.0% in September, back to January's 43.9%. Search-purpose crawling went the other way, rising in seven of the eight months since January: 2.6% in January, 5.6% in July, 8.4% in August, 10.6% in September. Add user-action fetches and the retrieval side of AI crawling reached 13.7% in September, up from 4.8% in January.
| Purpose | Panel, Jan | Panel, Jul* | Radar, Jan | Radar, Jul | Radar, Aug | Radar, Sep |
|---|
| Training | 39.1% | 46.1% | 43.9% | 50.7% | 48.2% | 44.0% |
| Search | 8.3% | 12.4% | 2.6% | 5.6% | 8.4% | 10.6% |
| User action | 2.1% | 2.5% | 2.2% | 2.6% | 4.7% | 3.1% |
| Mixed purpose | 50.0% | 38.3% | 50.9% | 39.9% | 37.1% | 40.5% |
| Undeclared | n/a | n/a | 0.5% | 1.2% | 1.6% | 1.8% |
* Panel figures for July 2026 cover July 1-21 (partial month); panel columns leave undeclared-purpose crawling as the small remainder. Radar: global crawl-purpose shares, calendar months of 2026, pulled October 10, 2026.
Compare panel and Radar on direction here, not on level. Cloudflare revised its crawl-purpose classification after our July edition: Radar's July 2026 now reads 50.7% training and 5.6% search, where it read 44.7% and 11.6% when we published on August 28. The mixed and user-action shares didn't move, so roughly six points were reclassified from search to training. Our panel figures were classified before that revision. On both versions the direction is the same: training rose into the summer, and search has climbed since.
If August and September hold, AI crawling is tilting from ingestion toward retrieval, and retrieval is the kind of crawl that can turn into a citation, the thing our AI visibility tracker exist to count.
💡Quick Insight: Search-purpose crawling was 10.6% of AI-bot requests worldwide in September 2026, four times January's 2.6% on Cloudflare Radar. A search crawl is a fetch an answer engine may cite; a training crawl is not.
What the bots fetch is shifting, too. HTML's share of AI-bot requests fell from 75.6% in January to 68.9% in September, while plain text more than doubled, from 4.0% to 9.2%. JavaScript (6.5%), JSON (6.1%) and images (5.0%) split most of the rest. Radar doesn't break the plain-text bucket down by file, so we can't say how much of the rise is robots.txt, llms.txt or anything else.
Training still runs the larger share of the crawl. Cloudflare's June 2026 report found 52% of crawler requests are now for AI training, up from 22% in Spring 2025. The run-up started earlier. HUMAN Security's 2026 benchmarks measured AI training crawler volume growing 136% across calendar 2025, with the steepest climb from August to October of that year.
If you publish docs, blog or changelog content, assume close to half of your AI-bot hits are still training crawls, and that the search share is the part growing. That raises the stakes of the allow-or-block decision below.
Which industries do AI crawlers hit hardest?
Three verticals absorb about two-thirds of all crawler traffic, and this is the most stable table in the report: September looks almost exactly like July.
| Vertical | Panel, Jul* | Radar, Jul | Radar, Sep |
|---|
| Shopping | 21.2% | 25.7% | 25.7% |
| Internet & telecom | 21.6% | 20.6% | 20.9% |
| Computer & electronics | 24.0% | 19.1% | 19.4% |
| News & media | 7.9% | 9.0% | 8.3% |
| Gambling | 4.0% | 6.9% | 6.3% |
| Finance | 2.7% | 2.6% | 2.8% |
| Games | 1.3% | 2.2% | 2.3% |
* Share of crawler hits on our panel, July 2026 (Jul 1-21). Radar: share of global crawler traffic by site vertical, calendar months of 2026.
Shopping leads globally at 25.7% of crawler traffic, the same in July and September. On our panel, computer and electronics led in July at 24.0%, with shopping third at 21.2%; software-heavy customers explain the swap. The number to flag for anyone running a store is the per-site load: shopping sites are about 20% of the sites we track but pulled 21.2% of the crawler hits, so a shop carries more crawler traffic per site than a software company does. Gambling has been easing all year, from 7.6% of global crawler traffic in January to 6.3% in September; professional services rose from 2.7% to 3.0%.
📌Pro Tip: If you run an e-commerce site, crawler management isn't optional. Shopping is the most-crawled vertical on the global web (25.7% of crawler traffic on Cloudflare Radar, September 2026) and pulled more hits per site than any other segment on our panel.
How often do AI crawlers get blocked?
More often every month. In September 2026, 38.1% of crawler requests worldwide were answered with a 4xx status on Cloudflare Radar, the highest month of the year, and the share served a clean 2xx fell to 46.6%. January's 4xx rate was 33.1%, July's 35.8% and August's 37.8%. Across the sites we monitor, the July rate (Jul 1-21) was 36.4%, within a point of Radar's.
| Status (global) | Jan | Jul | Aug | Sep |
|---|
| 200 served | 49.3% | 45.7% | 44.2% | 44.8% |
| 403 forbidden | 20.1% | 21.4% | 23.9% | 23.8% |
| 404 not found | 7.5% | 8.1% | 8.5% | 8.4% |
| 429 rate-limited | 4.4% | 5.2% | 4.3% | 4.8% |
| 301/302 redirect | 11.4% | 12.9% | 13.0% | 12.1% |
| All 4xx | 33.1% | 35.8% | 37.8% | 38.1% |
Cloudflare Radar, share of global crawler requests by response status, calendar months of 2026. Rows shown are the largest codes; 204, 304, 503 and other codes make up the remainder.
The wall is mostly 403s. Deliberate refusals were 23.8% of all crawler requests worldwide in September, nearly three times the 404s (8.4%), so the rejections are policy, not broken links. Rate limiting had its moment in June, when 429s spiked to 7.2% of global crawler requests, and has run between 4.3% and 5.2% since.
🔑Key Takeaway: More than 1 in 3 crawler requests worldwide (38.1% in September 2026) is rejected with a 4xx on Cloudflare Radar, up from 33.1% in January. 403s alone are now 23.8% of crawler requests.
Our crawl waste report breaks that wall down bot by bot (who eats the most rejections, and what it does to crawl budget), so it isn't repeated here.
robots.txt is the intent layer above those status codes. Across 4,257 top-domain robots.txt files our audit crawler parsed on July 20, 2026, the four most-named agents were all AI crawlers. Cloudflare Radar's global scan of 4,261 files on October 5, 2026 ranks the same four in the same order:
| Agent | Our crawl (Jul 20) | Radar (Oct 5) |
|---|
| GPTBot | 773 | 703 |
| ClaudeBot | 629 | 611 |
| Google-Extended | 578 | 563 |
| CCBot | 568 | 521 |
Counts are robots.txt files naming the agent. Ours: 4,257 top-domain files parsed July 20, 2026. Radar: 4,261 top-domain files parsed October 5, 2026.
Googlebot, the agent these files spent two decades addressing, is named in 412 files on Radar's October scan, fewer than eight AI-era agents, PerplexityBot, ChatGPT-User and OAI-SearchBot included. And the files are getting specific about which job a bot does. Training crawlers get disallowed far more often than allowed; search and user agents get allowed about as often as they get blocked:
| Agent | Job | Disallowed in | Allowed in |
|---|
| GPTBot | Training | 546 | 338 |
| ClaudeBot | Training | 473 | 296 |
| CCBot | Training | 452 | 179 |
| Bytespider | Training | 408 | 105 |
| Meta-ExternalAgent | Training | 329 | 129 |
| PerplexityBot | Search | 348 | 344 |
| ChatGPT-User | User action | 328 | 305 |
| OAI-SearchBot | Search | 279 | 316 |
| Claude-SearchBot | Search | 184 | 164 |
| Googlebot | Search | 314 | 290 |
Cloudflare Radar robots.txt scan, October 5, 2026: robots.txt files with at least one Disallow (or Allow) rule for the agent, out of 4,261 parsed. A file can carry both. Googlebot's disallows are almost all partial: only 27 files block it outright, against 360 for GPTBot.
How much traffic do AI crawlers send back?
A crawl-to-refer ratio is the number of pages a bot operator fetches for every referral visit its product sends back. It's the fairest single measure of whether a crawler is a trade or an extraction, and in September the operators most people think of as "search" moved in opposite directions.
| Operator | Panel, Jul* | Radar, Jan | Radar, Jul | Radar, Aug | Radar, Sep |
|---|
| Perplexity | 263:1 | 112:1 | 296:1 | 822:1 | 2,373:1 |
| Anthropic | 2,363:1 | 47,779:1 | 1,914:1 | 910:1 | 549:1 |
| OpenAI | 179:1 | 1,309:1 | 256:1 | 424:1 | 341:1 |
| Mistral | 6,021:1 | 23:1 | 29,944:1 | no referrals | no referrals |
| Microsoft | 35:1 | 36:1 | 36:1 | 37:1 | 40:1 |
| Google | 4:1 | 4.7:1 | 4.8:1 | 5.2:1 | 4.7:1 |
| DuckDuckGo | 3:1 | 1.4:1 | 2.4:1 | 1.8:1 | 3.6:1 |
* Pages crawled per referral session on our panel, July 2026 (Jul 1-21). Radar: global crawl-to-refer ratio by operator, calendar months of 2026. Radar reports Mistral's August and September ratios as undefined: crawling with no measurable referrals.
Perplexity is September's extraction story. Its ratio climbed from 112:1 in January to 2,373:1 in September, and most of that happened after July, the same months PerplexityBot's crawl share grew sixfold. Anthropic kept going the other way: on Radar it went from 47,779:1 in January to 549:1 in September (on our panel it was about 57,000:1 in January and 2,363:1 in July). OpenAI has settled in the 250-450:1 range since July. Mistral has sent no measurable referrals at all since August. The classic search engines sit at 2:1 to 5:1 by design, and Baidu is the one to watch among them: 3.7:1 in January, 39.6:1 in September. The full extraction-gap analysis, month by month, lives in our crawl-to-refer deep dive.
Should you allow or block AI crawlers?
Allow the bots that cite you and fetch for users; treat training-only bots as a business decision. That's the whole framework. The September data just sharpens each side of it.
| Bot class | Examples | Call |
|---|
| Search / citation | OAI-SearchBot, PerplexityBot | Allow |
| User action | ChatGPT-User, Claude-User | Allow |
| Training only | GPTBot, CCBot, Bytespider | Case-by-case |
A blanket rule would be simpler than "case-by-case," but a blanket rule is exactly how sites end up blocking the bots that send them readers.
- Blocking search and user-action bots (Claude-SearchBot included) removes your pages from the answers those engines write: you lose citations and referrals and gain nothing, which defeats the whole point of answer engine optimization. With search crawling at 10.6% of AI-bot requests and rising every month, that's the growing part of the crawl. The referral economics are thin but real. 2025 Stanford Graduate School of Business research, summarized in Arc XP's analysis, put click-through rates from AI chatbots at 0.33% and AI search engines at 0.74%, against 8.6% for Google Search. Thin, but a citation carries brand value a click-through rate doesn't capture.
- Training-only bots are the real negotiation. GPTBot's training use, CCBot, and Bytespider take corpus value and send nothing back on any timescale you can measure. Training is still 44.0% of AI-bot requests worldwide, so a blanket "allow all" gives a lot away.
- The answer isn't permanent, in either direction. Anthropic's ratio fell from 47,779:1 in January to 549:1 in September, so a bot worth blocking in January can be worth allowing by September. Perplexity went from 112:1 to 2,373:1 over the same stretch. Revisit the call monthly, per operator.
🚩Red Flag: Blocking Claude-SearchBot, OAI-SearchBot, or ChatGPT-User removes your pages from the answers those engines write. You lose citations and referrals while the training debate carries on without you.
AI crawler directory: who runs what
The decision only works if you can tell the bots apart, and the naming doesn't help: three Anthropic agents, three OpenAI agents, three Google agents, each with a different job. Roles below come from Cloudflare Radar's bot directory as of October 10, 2026, translated into plain words (Radar's AI_CRAWLER is a training crawler; AI_SEARCH and SEARCH_ENGINE_CRAWLER are search crawlers; AI_ASSISTANT is a user-action fetcher).
| Agent | Operator | Role |
|---|
| GPTBot | OpenAI | Training crawler |
| OAI-SearchBot | OpenAI | Search crawler |
| ChatGPT-User | OpenAI | User-action fetcher |
| ClaudeBot | Anthropic | Training crawler |
| Claude-SearchBot | Anthropic | Search crawler |
| Claude-User | Anthropic | User-action fetcher |
| Meta-ExternalAgent | Meta | Training crawler |
| Amazonbot | Amazon | Training crawler |
| Applebot | Apple | Search crawler |
| GoogleOther | Google | Training crawler |
| Google-CloudVertexBot | Google | Training crawler |
| Bravebot | Brave | Search crawler |
| Grok Bot | xAI | User-action fetcher |
| MistralAI-User | Mistral AI | User-action fetcher |
Source: Cloudflare Radar bot directory (radar/bots), October 10, 2026. We left out the directory's robots.txt-compliance flag on purpose: it didn't match every operator's published documentation when we cross-checked, so read each operator's own crawler page before you rely on a rule being honored.
If you differentiate, do it precisely. Our robots.txt guide covers per-agent directives, CDN-level tools like Cloudflare's AI Crawl Control expose the same allow/block levers per bot, and our llms.txt guide covers the proposed companion file (adoption is real; measured impact isn't yet).
How to run this report on your own site
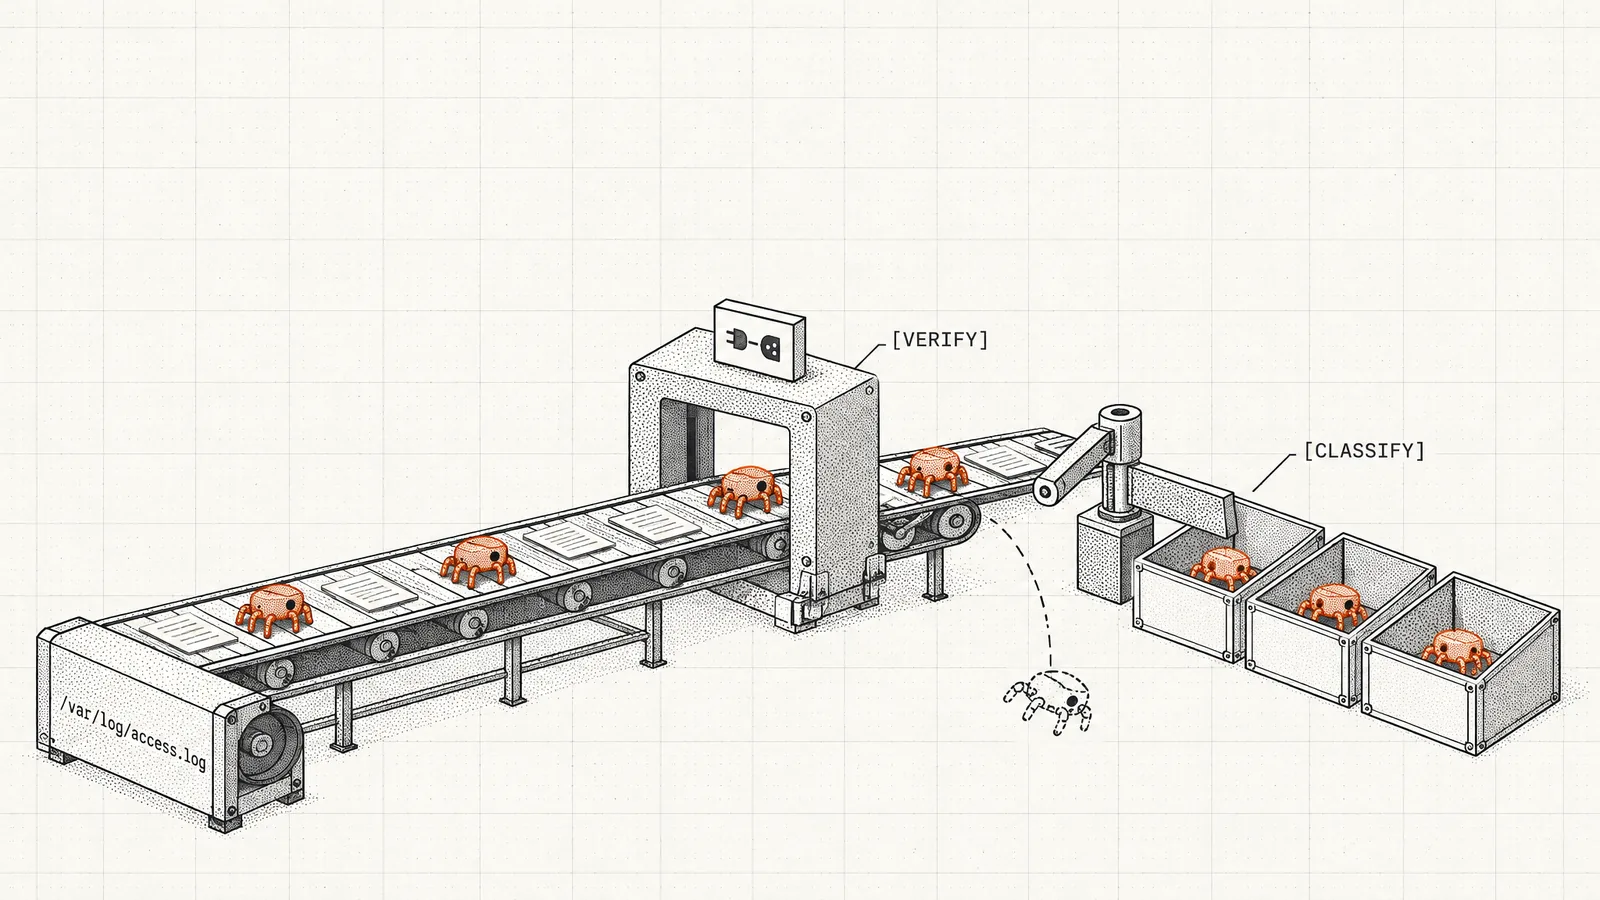
Every number in this AI crawler report comes from a repeatable pipeline: logs in, user agents verified and mapped, purposes classified, blocks and referrals counted. You can run the same report on one site with an afternoon of work. No global dashboard will tell you what's crawling your pages.
- Pull 30 days of raw access logs from your origin or CDN. You need four fields per request: user agent, IP, path, and status code.
- Verify before you count. Check claimed Googlebot, GPTBot, or ClaudeBot hits against reverse DNS or the operator's published IP ranges. This is the step most often skipped, and spoofed agents are common enough that skipping it quietly invalidates the rest of the report.
- Map user agents to operators, keeping roles separate. ClaudeBot, Claude-SearchBot, and Claude-User all belong to Anthropic but do different jobs; your report should never merge them. The directory above is the starting map.
- Classify each bot's purpose (training, search, user action) from the operator's own documentation, then compute your purpose mix and compare it against the Radar figures above.
- Compute your block rate and referral ratio. Share of verified bot requests answered 4xx per agent, checked against what your robots.txt says you intend. Drift between the two is where crawl budget dies. Then segment sessions referred from chatgpt.com, perplexity.ai, and friends to get your own crawl-to-refer ratio.
- Repeat monthly and read deltas, not levels. One month is trivia. ClaudeBot's spike-and-cool only meant something because May, June, July and August sat side by side, and Perplexity's sixfold rise only shows up against its flat first half.
📌Pro Tip: Never trust a user-agent string on its own. Verify claimed bot hits with a reverse-DNS lookup or the operator's published IP ranges before they enter your report. Spoofed agents will otherwise inflate every number in it.
This is also the pipeline SEOmator AI Traffic Analytics automates. It's the instrument behind every panel number in this post: it classifies AI-bot hits, purposes, block rates, and referrals across 500+ sites and 50M+ tracked users a month. If you'd rather start smaller, a free SEO audit flags robots.txt and crawlability problems in about a minute, and our GEO audit tool checks how your pages read to the answer engines these crawlers feed.
Previous editions
The July edition (published August 28, 2026) led with ClaudeBot. Anthropic's training crawler more than doubled its share of the AI-bot user-agent mix on our panel between May and June 2026, then gave part of it back:
| AI bot user agent | May | Jun | Jul* |
|---|
| Googlebot | 27.7% | 26.0% | 25.5% |
| ClaudeBot | 10.7% | 22.4% | 19.2% |
| Meta-ExternalAgent | 13.8% | 10.7% | 12.7% |
| GPTBot | 11.5% | 9.2% | 9.9% |
| Bytespider | 9.7% | 7.1% | 5.4% |
| Claude-SearchBot | 2.5% | 3.7% | 3.9% |
* Share of the AI-bot user-agent mix on our panel; July 2026 covers July 1-21 (partial month).
Globally the same curve ran one notch lower: ClaudeBot went from 9.9% of AI-bot traffic in May to 19.8% in June and 16.5% in July on Cloudflare Radar, while Meta-ExternalAgent rebounded from 10.2% to 12.5%. The edition read the shape as a bulk re-crawl cycle finishing rather than a permanent step-change. August and September confirmed it: ClaudeBot sat at 11.9% and 12.0%, January's level, and Meta-ExternalAgent took the #2 spot at 14.1% in August.
Methodology and sources
Global data. Source: Cloudflare Radar — radar/bots/summary/bot_operator, radar/ai/bots/summary/user_agent, radar/ai/bots/summary/crawl_purpose, radar/ai/bots/summary/content_type, radar/bots/crawlers/summary/response_status, radar/bots/crawlers/summary/response_status_category, radar/bots/crawlers/summary/vertical, radar/bots/crawlers/summary/crawl_refer_ratio, radar/robots_txt/top/user_agents/directive, radar/bots (radar.cloudflare.com), pulled October 10, 2026. Every global figure is a calendar month of 2026, January to September. The robots.txt scan is dated October 5, 2026 (4,261 files parsed); disallow and allow counts use the directive filter, and a file can carry both. Radar shares are percentage-normalized; we cite rankings and shares, not absolute request volumes. Two revision notes: Radar reclassified crawl purpose after our July edition (July now reads 50.7% training and 5.6% search, against 44.7% and 11.6% when we published), and the July edition's August figures covered Aug 1-28, where this edition uses full months.
Panel data. All "panel" and "sites we track" figures come from SEOmator Agent Analytics: 500+ sites and 50M+ users tracked monthly, January-July 2026. The panel skews toward the business web (roughly 60% B2B SaaS, 20% e-commerce, 20% mixed), so panel shares describe that population, never the web at large. July 2026 panel figures are partial, covering July 1-21, and the panel has not been re-derived for August or September, so its columns stop at July. Panel crawl purposes were classified before Radar's revision, so compare them with Radar on direction, not level. Anthropic appears as a distinct operator in both datasets from June 2026, when Radar's bot classification expanded (our panel follows the same taxonomy). robots.txt figures come from our audit crawler: 4,257 top-domain robots.txt files parsed on July 20, 2026.
Cadence. This report refreshes monthly on this URL. Prior editions are archived on-page as each new month is published, so month-over-month claims stay checkable.
FAQ
What is an AI crawler report?
An AI crawler report tracks how AI bots access a site or the wider web: traffic share by crawler and operator, crawl purpose mix (training, search, user action), block rates, robots.txt directives, and crawl-to-refer ratios. Monthly editions matter because shares move fast: on Cloudflare Radar, ClaudeBot doubled its share of AI-bot traffic in a single month in 2026, and PerplexityBot grew sixfold in two.
What changed in AI crawler activity in September 2026?
Search crawling grew and OpenAI's training crawler shrank. Search-purpose crawling reached 10.6% of AI-bot requests worldwide on Cloudflare Radar, up from 5.6% in July, while training fell to 44.0% from its 52.6% June peak. GPTBot dropped to 6.2% of AI-bot traffic as OAI-SearchBot rose to 3.6%, and PerplexityBot reached 2.2%. Rejection rates hit a 2026 high, with 38.1% of crawler requests answered 4xx.
Is ChatGPT a web crawler?
No. ChatGPT is an application; the crawling happens under separate OpenAI user agents. GPTBot collects training data, OAI-SearchBot powers search and citations, and ChatGPT-User fetches a page live when a user asks about it. Each can be addressed separately in robots.txt, so you can stay citable in ChatGPT while opting out of model training.
What are the main AI crawler bots in 2026?
On Cloudflare Radar in September 2026, the biggest AI-bot user agents were Googlebot (24.5%), Meta-ExternalAgent (13.1%), ClaudeBot (12.0%), Applebot (8.5%), Bingbot (7.6%), Amazonbot (6.2%), GPTBot (6.2%) and OAI-SearchBot (3.6%), with Bytespider, Claude-SearchBot and PerplexityBot behind them. The ordering shifts month to month.
Which AI crawlers should I block, and which should I allow?
Allow search and user-action bots (OAI-SearchBot, Claude-SearchBot, ChatGPT-User, Claude-User, PerplexityBot): they produce citations and referrals. Decide separately on training-only crawlers (GPTBot's training use, CCBot, Bytespider), which take corpus value without sending traffic back. Blanket blocks remove you from AI answers entirely; blanket allows give away training value silently.
How do I stop AI crawlers I don't want?
Name each agent in robots.txt with a Disallow rule; the major AI crawlers honor it. robots.txt is a request, not a wall, so pair it with server or CDN enforcement (4xx responses, bot management rules, tools like Cloudflare's AI Crawl Control) for agents that ignore directives. The rising 403 rates on Cloudflare Radar (23.8% of global crawler requests in September 2026) show many sites already enforce this way.
How do I track AI crawler bots on my site?
Parse server or CDN logs for known AI user agents, verify them against reverse DNS or published IP ranges, then group by operator and purpose. Watch four numbers monthly: share per bot, purpose mix, 4xx block rate, and AI referrals. An analytics layer that classifies AI bots automatically, like the Agent Analytics panel behind this report, replaces the manual pipeline.
Does blocking AI crawlers hurt AI Overviews visibility?
Google's AI Overviews draw on standard Googlebot indexing, so blocking Google-Extended (the Gemini training opt-out) doesn't remove you from AI Overviews; blocking Googlebot itself would. The bigger risk is legacy blanket rules written against training crawlers that also catch citation bots like OAI-SearchBot or Claude-SearchBot, silently removing you from other engines' answers.
Meta's crawler is ahead now. ClaudeBot spiked to 19.8% of AI-bot traffic on Cloudflare Radar in June, then settled back to 11.9% in August and 12.0% in September, its January level. Meta-ExternalAgent took the #2 spot behind Googlebot in August (14.1%) and held it in September (13.1%).
What does a Cloudflare AI crawler report show?
Cloudflare Radar's AI insights show global, percentage-normalized shares: bot traffic by operator, AI-bot traffic by user agent, crawl-purpose mix, content types fetched, response codes, crawler traffic by industry vertical, crawl-to-refer ratios, and which agents robots.txt files name most often. It describes the internet at large. Pair it with your own log data or a panel view: a global average can't tell you what's crawling your site, or why.