A robots.txt file is a plain-text file at the root of a site that tells crawlers which URLs they may request. It controls crawling, not indexing: a blocked URL can still show up in Google. In 2026 its busiest job is AI. On the top 1,000 domains we checked, 21.0% of robots.txt files fully block at least one AI crawler.
That last number is new, and it's why this guide was rewritten. The syntax hasn't changed in years, but who you're writing rules for has: a robots.txt file now talks to training crawlers, AI search crawlers and user-triggered agents as well as Googlebot, and each one reads its own line.
What is a Robots.txt File?
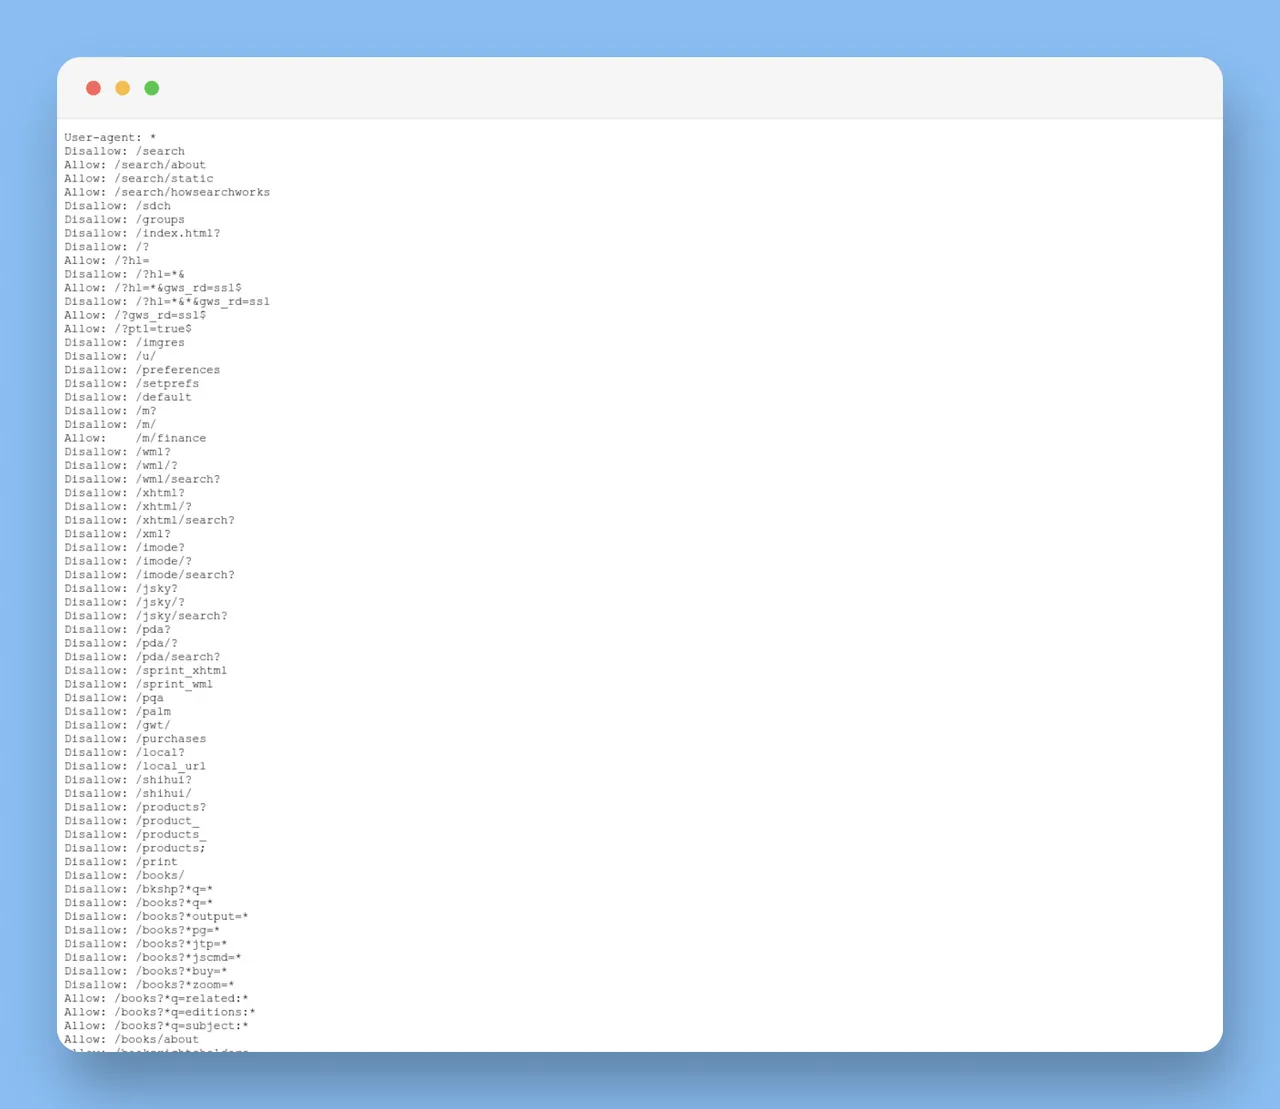
Robots.txt is a plain text file located in the root directory of a website. Its primary function is to instruct web robots (a.k.a crawlers or spiders) on how to interact with the website. The "Robots Exclusion Protocol" it uses, standardised as RFC 9309 in 2022, offers a series of directions to inform bots about which URLs they can or cannot request.
Think of it as a signpost rather than a lock. Reputable crawlers read it and follow it, but the RFC itself is blunt that its rules "are not a form of access authorization". Anyone can read your robots.txt, and anything that ignores it can still fetch your pages.
Why is Robots.txt Important?
Now, you might be asking yourself why learning about the robots.txt file matters to you as a marketer or SEO expert. Here are the key reasons:
Crawl control: Robots.txt steers crawlers away from URLs that waste their time, such as internal search results, faceted filters and cart pages, and points them to your sitemap.
Crawl Budget Optimization: A robots.txt file can optimize your crawl budget by preventing search engine bots from spending requests on irrelevant URLs. Google's own crawl budget guide is written for large sites (1 million+ pages) and fast-changing medium sites (10,000+ pages), so on a small site this is rarely the constraint.
AI crawler control: Robots.txt is where you decide which AI companies may use your pages for model training, and which may fetch them to answer questions in AI search. Those are separate crawlers with separate rules, covered in detail below.
Remember, an incorrect robots.txt setup can bar search engine bots from crawling your site altogether, affecting your SEO. A leftover Disallow: / from a staging site is the most expensive robots.txt mistake I know of, because nothing breaks visibly until traffic falls.
How Does a Robots.txt File Work?
The working principle of a robots.txt file is fairly simple. When a well-behaved bot wants to request a URL, it first checks the robots.txt file at the root of that host. If its rules allow the URL, it crawls it. Whether the page then gets indexed is a separate decision the search engine makes later.
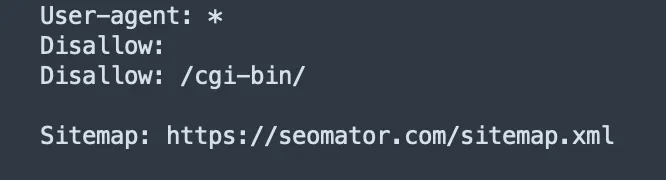
The structure of a robots.txt file usually consists of "User-agent" followed by "Disallow" or "Allow" directives.
- User-agent: This is the web crawler that the rule applies to.
- Disallow: The instruction telling the user-agent not to crawl a particular URL.
- Allow: The directive that permits user-agents to crawl a URL (used mainly for granting access to subdirectories in an otherwise disallowed directory).
For further reading, see Google's guide to creating a robots.txt file.
⚠️Common Mistake: Using robots.txt to keep a page out of Google. Google says robots.txt "is not a mechanism for keeping a web page out of Google". A blocked URL can still be indexed from links pointing to it; use noindex or a password instead.
Understanding the Terminology and Syntax
To use robots.txt well, you need to understand its vocabulary: the terminology and syntax of the robots.txt file.
The User-Agent Directive
The User-Agent is at the heart of any robots.txt file. Every rule below it applies to the crawler it names.
A User-agent in the context of a robots.txt file is the product token of a crawler. Some commonly known User-agents include Googlebot for Google Search, Bingbot for Bing, and GPTBot and ClaudeBot for OpenAI's and Anthropic's training crawlers.
The User-Agent line in the robots.txt file is written as -
User-agent: [name-of-the-crawler]
For instance, if you want to address Google's crawler, the User-agent will look like this:
User-agent: Googlebot
On the other hand, when you want all bots to follow the set of directives, you'd use an asterisk (*) like so:
User-agent: *
A crawler obeys the most specific group that names it and ignores the rest. So if you write a User-agent: GPTBot group, GPTBot stops reading your User-agent: * rules entirely.
The Disallow Directive
After specifying the User-agent, it's time to lay down some ground rules. That's where the Disallow directive comes into play.
The Disallow directive tells the bot which paths it should not crawl. If you want to prevent crawlers from requesting a specific page or folder, you use Disallow.
Here's what a Disallow directive looks like:
Disallow: /page-link/
The Allow Directive
Sometimes, we want to allow certain exceptions, and that is where the Allow rule comes in handy.
Allow is particularly useful when you want to grant access to a particular subdirectory or page in an otherwise disallowed directory.
Consider the following example:
User-agent: *
Disallow: /folder/
Allow: /folder/important-page.html
In this case, the general rule is not to access /folder/, but there's an exception, important-page.html, which may be crawled.
The Sitemap Directive
This directive makes it easier for search engines to find your sitemap. Sitemap URLs are written on individual lines preceded by 'Sitemap':
Sitemap: https://www.yourwebsite.com/sitemap.xml
It's the most widely used optional line: 68.7% of the robots.txt files in our top-1,000 check include one.
Use Wildcards to Clarify Directions
You can use the * wildcard character in Disallow and Allow directives to match any sequence of characters. For example:
Disallow: /*? Disallows any URLs that include a ? .
Use '$' to Indicate the End of a URL
If you want to match a specific file type or to avoid ambiguity in URLs, use the dollar sign ($) at the end of the URL. For example, Disallow: /*.jpg$ will disallow all .jpg files.
Hash symbols can be used for comments for your future reference. For example:
# Blocks access to everything under /private/
Disallow: /private/
Mind the trailing slash. Rules match URL prefixes, so Disallow: /private would also block /private-events/ or /private.html: any path that merely starts with the same characters.
The Function of a Robots.txt File
Now that we've covered what a robots.txt file is and its syntax, here's what it's actually good for in practice.
Optimize Crawl Budget
Crawl budget refers to the number of URLs a search engine crawler can and wants to crawl on your site. Using it efficiently matters most on large sites, where crawlers can't get through everything.
Too many unimportant URLs can clog the queue, making it harder for crawlers to reach the pages that matter. The robots.txt file lets these crawlers know which areas they can skip, saving crawl budget for important pages. Our crawl waste report shows where that budget typically leaks.
Keep Crawlers Out of Low-Value Areas
Often a website has URLs that are necessary for functionality but useless in search: admin pages, internal search results, cart and checkout steps. Disallowing them keeps crawlers focused on content that should rank.
Duplicate content is the exception. Don't disallow duplicates: a crawler that can't fetch a page can't see its canonical tag either, so the duplicate's signals never get consolidated. Point duplicates at the preferred URL with a canonical tag instead, as our guide to canonical issues explains.
Hide Resources from Crawlers, Not from People
Some files are meant for internal use only, like internal documents, exports or images. A well-crafted robots.txt file can stop Google and other reputable crawlers from fetching such material. It can't guarantee the URLs stay out of search results, because Google can still list a blocked URL it finds through links.
It's very important to note that robots.txt is not a security measure. The file is public, so listing a sensitive path in it advertises that path. For secure content, always use proper password protection or other security measures.
🚩Red Flag: A line like Disallow: /admin-backup/ tells every visitor, human or bot, exactly where to look. Put sensitive areas behind authentication instead of naming them in a public file.
If you'd like to learn more, check out Google's official documentation on blocking indexing with noindex.
Robots.txt and AI crawlers
AI companies don't run one crawler each. Most run separate crawlers for model training, for their AI search results, and for pages a user asks the assistant to open, and each one reads its own User-agent line. Blocking one doesn't block the others.
To see how sites actually use this, we fetched robots.txt from the 1,000 highest-ranked domains on the Tranco list on 26 September 2026. 514 of them served a valid file (many top domains are CDNs and APIs with no website). Here's how often each crawler is named, and how often it's blocked from the whole site:
| Token | Operator | Purpose | Named | Fully blocked |
|---|
| GPTBot | OpenAI | Training | 25.3% | 12.6% |
| OAI-SearchBot | OpenAI | ChatGPT search | 17.1% | 4.7% |
| ChatGPT-User | OpenAI | User requests | 19.1% | 6.4% |
| ClaudeBot | Anthropic | Training | 23.7% | 13.2% |
| Claude-SearchBot | Anthropic | Claude search | 13.2% | 5.4% |
| Claude-User | Anthropic | User requests | 13.8% | 6.8% |
| Google-Extended | Google | Gemini training | 22.0% | 10.5% |
| PerplexityBot | Perplexity | Perplexity search | 22.8% | 9.3% |
| CCBot | Common Crawl | Web archive | 22.8% | 14.6% |
| Bytespider | ByteDance | Crawler | 20.4% | 15.0% |
| Googlebot | Google | Google Search | 15.8% | 0.2% |
Source: SEOmator check of robots.txt files on the Tranco top 1,000 domains, fetched 26 September 2026; 514 domains served a valid file. "Fully blocked" means the bot's group disallows / with no Allow rules. Crawler purposes are taken from each operator's documentation.
Overall, 34.2% of those files name at least one AI crawler, and 21.0% fully block at least one. Another 7.4% block every bot they don't name, with User-agent: * and Disallow: /.
📊By the Numbers: On the top 1,000 domains (26 September 2026), GPTBot was fully blocked in 12.6% of robots.txt files, but OpenAI's search crawler, OAI-SearchBot, in only 4.7%. Sites are opting out of training while staying visible in AI search.
The split between training and search is the pattern to notice. ClaudeBot is fully blocked more than twice as often as Claude-SearchBot (13.2% against 5.4%), the same shape as OpenAI's pair. That's deliberate, and the operators support it: OpenAI says its two settings are "independent of the others", so a site can allow OAI-SearchBot to appear in ChatGPT search while blocking GPTBot from training.
Three details trip people up:
- Google-Extended doesn't touch Google Search. Google says it "does not impact a site's inclusion in Google Search nor is it used as a ranking signal". It controls Gemini training and grounding. Because AI Overviews are part of Search, blocking Google-Extended won't take you out of them.
- User-triggered agents may not obey robots.txt. OpenAI says that for ChatGPT-User, "because these actions are initiated by a user, robots.txt rules may not apply". Treat those tokens as a signal of intent, not a wall.
- Nobody blocks Googlebot. Only one site in the sample (0.2%) blocked it completely. The AI rules sit next to Google rules, not in place of them.
If you want to stay out of training but visible in AI answers, a common pattern looks like this:
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: OAI-SearchBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /
Before you block training crawlers, weigh what they give back. Our crawl-to-refer ratio analysis measures how many pages each AI operator crawls for every visit it sends, and the monthly AI crawler report tracks which bots are growing. Robots.txt is also only one of the files AI systems read; see our llms.txt adoption study for the other.
🔑Key Takeaway: Decide per purpose, not per company. Block the training tokens you object to, and keep the search tokens open if you want to be cited in AI answers.
What Google ignores in robots.txt
Plenty of robots.txt lines do nothing for Google. These come from Google's robots.txt specification, with how often each still turns up in our top-1,000 sample:
| Rule or behaviour | What Google does | Top-1,000 files |
|---|
crawl-delay | Not supported, ignored | 12.8% still use it |
noindex in robots.txt | Support retired 1 September 2019 | 0.4% still use it |
| Files over 500 KiB | Content past 500 KiB is ignored | 0 in our sample |
| Caching | Cached for up to 24 hours, sometimes longer | n/a |
| 4xx response (except 429) | Treated as if no file exists: no restrictions | n/a |
| 5xx response | Crawling stops for the first 12 hours | n/a |
The noindex line is the one that still costs people traffic. Google announced in 2019 that it had retired support for it, so a page "noindexed" only in robots.txt stays indexable. Use a robots meta tag or an X-Robots-Tag header instead.
The caching rule explains a common panic. After you fix a robots.txt mistake, Google can keep acting on the old file for up to a day, so don't expect crawling to resume the minute you deploy.
💡Quick Insight: 12.8% of the top 1,000 domains' robots.txt files still set crawl-delay. Bing honours it; Google doesn't, and adjusts its crawl rate from how your server responds instead.
Creating and Implementing a Robots.txt File
Creating a robots.txt file takes a few minutes and no special tools. Here are the steps.
Create a File and Name It Robots.txt
Start by creating a new text file. You can do this with any simple text editor like Notepad (Windows) or TextEdit (Mac). Once you have a blank document open, save the file as robots.txt, all lowercase: URLs are case-sensitive, so a file saved as Robots.txt or ROBOTS.TXT won't be found at /robots.txt.
Add Directives to the Robots.txt File
Think about what you want to allow or disallow, and start entering directives based on this. Here's a very basic example:
User-agent: *
Disallow: /private/
This tells all bots (because of the * wildcard) not to crawl anything under the /private/ directory.
Upload the Robots.txt File
Once your robots.txt file is ready, you need to upload it to the root directory of your website. This is typically the same place where your website's main index.html file is located. Remember, the robots.txt file must be placed at the root (e.g., www.yourwebsite.com/robots.txt) to be found and recognized by bots.
How to Find a Robots.txt File
To see if a robots.txt file is in place or access yours, simply type /robots.txt at the end of your website's main URL in your web browser.
Test Your Robots.txt
Finally, test your robots.txt file to make sure it blocks and allows what you intended. SEOmator's Robots.txt Tester Tool checks any URL against a site's live rules. In Google Search Console, the robots.txt report (under Settings) shows which robots.txt files Google found, when it last fetched them, and any parsing errors. It replaced the old robots.txt Tester.
📌Pro Tip: Test the exact URLs you care about, not just the homepage. A rule like Disallow: /*? can quietly block every paginated or filtered URL on a site while the homepage tests fine.
Insight Into Robots.txt Best Practices
With the basics in place, a few best practices separate a robots.txt file that works from one that quietly causes problems.
Don't Block CSS and JS Files in Robots.txt
One key rule is to avoid blocking JavaScript and CSS files. These files are essential for Googlebot to understand your website's content and structure.
Previously, blocking such files wasn't seen as an issue, but Googlebot now renders pages much like a browser, so it needs access to these files to analyze the page.
Adding CSS or JS files to the Disallow directive could result in suboptimal rankings, as Google may not fully understand your page layout or its interactive elements.
Use Separate Robots.txt Files for Different Subdomains
If your website has multiple subdomains, you need to remember that each subdomain requires its own robots.txt file. For example, if you have a blog on a subdomain (like blog.yourwebsite.com), you need a separate robots.txt file at blog.yourwebsite.com/robots.txt.
This is because crawlers treat each host as a separate site. Overlooking this detail could lead bots to crawl, or skip, areas of your site contrary to your intentions.
SEO Best Practices for Robots.txt
Here are a few SEO-focused best practices for robots.txt:
Avoid Blocking Search Engines Entirely: Blocking all search engine bots can result in your site not being crawled at all. Use Disallow judiciously and only for specific parts of your site that crawlers don't need.
Don't use it for URL Removal: If you want a URL to be removed from search engine results, using robots.txt to disallow that URL isn't the best way, as it can still appear in the results due to external links pointing to it. Instead, use methods like "noindex", the Removals tool, or password protection; our guide to removing URLs from Google walks through each.
Link to your XML Sitemap: An excellent practice is to use robots.txt to link to your XML Sitemap. This increases the chances of bots finding your sitemap and discovering your pages faster.
Decide on AI crawlers deliberately: Write explicit groups for the AI crawlers you want to block or allow instead of relying on User-agent: *, so your intent is clear to every operator.
For more detail, see Google's introduction to robots.txt.
Conclusion: The Integral Role of Robots.txt in SEO
You've now covered what robots.txt is, its syntax, what it's good for, how AI crawlers read it, what Google ignores, and how to create and test the file.
Pros and Cons of Using Robots.txt
Like all optimization strategies, robots.txt comes with its advantages and potential pitfalls:
Pros:
- Control Over Crawling: robots.txt gives you a simple way to direct bots where they should and shouldn't go on your site.
- Crawl Budget Optimization: It enables the efficient use of your crawl budget by guiding crawlers to the important areas of your website.
- AI Opt-Outs: It's where you tell AI companies whether they may train on your content or fetch it for their search results.
Cons:
- Voluntary, Not Enforced: Bots can ignore your robots.txt, especially malicious bots that scan for weaknesses on your site. RFC 9309 says outright that its rules are not access authorization.
- Can Cause Crawlability Issues: In cases of misconfiguration, you can accidentally block bots from crawling your site.
The Impact of Robots.txt on Crawl Budget and SEO
A well-structured robots.txt file helps search engines spend their crawl on the parts of your site that deserve it. On a large site that can speed up how quickly new and updated pages are discovered; on a small site, its main SEO job is simply not to block anything important.
Future Directions in Robots.txt Usage
Robots.txt was an unofficial convention for almost thirty years before RFC 9309 standardised it in 2022. The pressure on it now comes from AI. The list of AI crawler tokens grows every year, and sites are responding: a third of the top 1,000 domains' files already name at least one AI crawler.
Two newer signals sit alongside it. Some sites add Content-Signal lines to state how their content may be used by AI, which we found in 2.9% of top-1,000 files. Others publish an llms.txt file to guide AI systems toward their best content. Neither replaces robots.txt, which remains the one file every major crawler agrees to read first.
Frequently Asked Questions
What is robots.txt used for?
Robots.txt tells crawlers which URLs on a site they may request. Site owners use it to keep crawlers out of low-value areas like internal search and cart pages, to point them to the sitemap, and increasingly to decide which AI crawlers may use the site for training or AI search.
Does robots.txt actually work?
For reputable crawlers, yes: Googlebot, Bingbot, GPTBot, ClaudeBot and similar bots follow it. It isn't enforced, though. RFC 9309 says its rules are not access authorization, malicious bots ignore it, and OpenAI says robots.txt rules may not apply to user-triggered visits by ChatGPT-User.
Can a page blocked by robots.txt still be indexed?
Yes. Robots.txt stops crawling, not indexing, so Google can still index a blocked URL it finds through links, usually without a description. Search Console reports these as "Indexed, though blocked by robots.txt". To keep a page out of results, allow crawling and add a noindex tag.
Should I block AI crawlers in robots.txt?
It depends on what you want from AI. Blocking training crawlers like GPTBot and ClaudeBot keeps your content out of future model training. Blocking search crawlers like OAI-SearchBot, Claude-SearchBot and PerplexityBot removes you from those AI search results. On the top 1,000 domains, sites block training crawlers more than twice as often as search crawlers.
Does blocking Google-Extended remove my site from AI Overviews?
No. Google says Google-Extended "does not impact a site's inclusion in Google Search". It controls whether your content is used for Gemini training and grounding. AI Overviews are part of Google Search, so they follow your Googlebot rules instead.
Does Google support crawl-delay or noindex in robots.txt?
No to both. Google's specification lists crawl-delay as unsupported, and Google retired support for noindex in robots.txt on 1 September 2019. Use a robots meta tag or X-Robots-Tag header for noindex. Google sets its crawl rate from your server's responses.
You May Also Read: