
· 17 min read
Single Page Application SEO: 9 Fixes (555-Site Test)
We tested 390 top homepages: 36% of React or Vue sites without a meta-framework hid most of their text from AI crawlers. Here are 9 SPA SEO fixes.
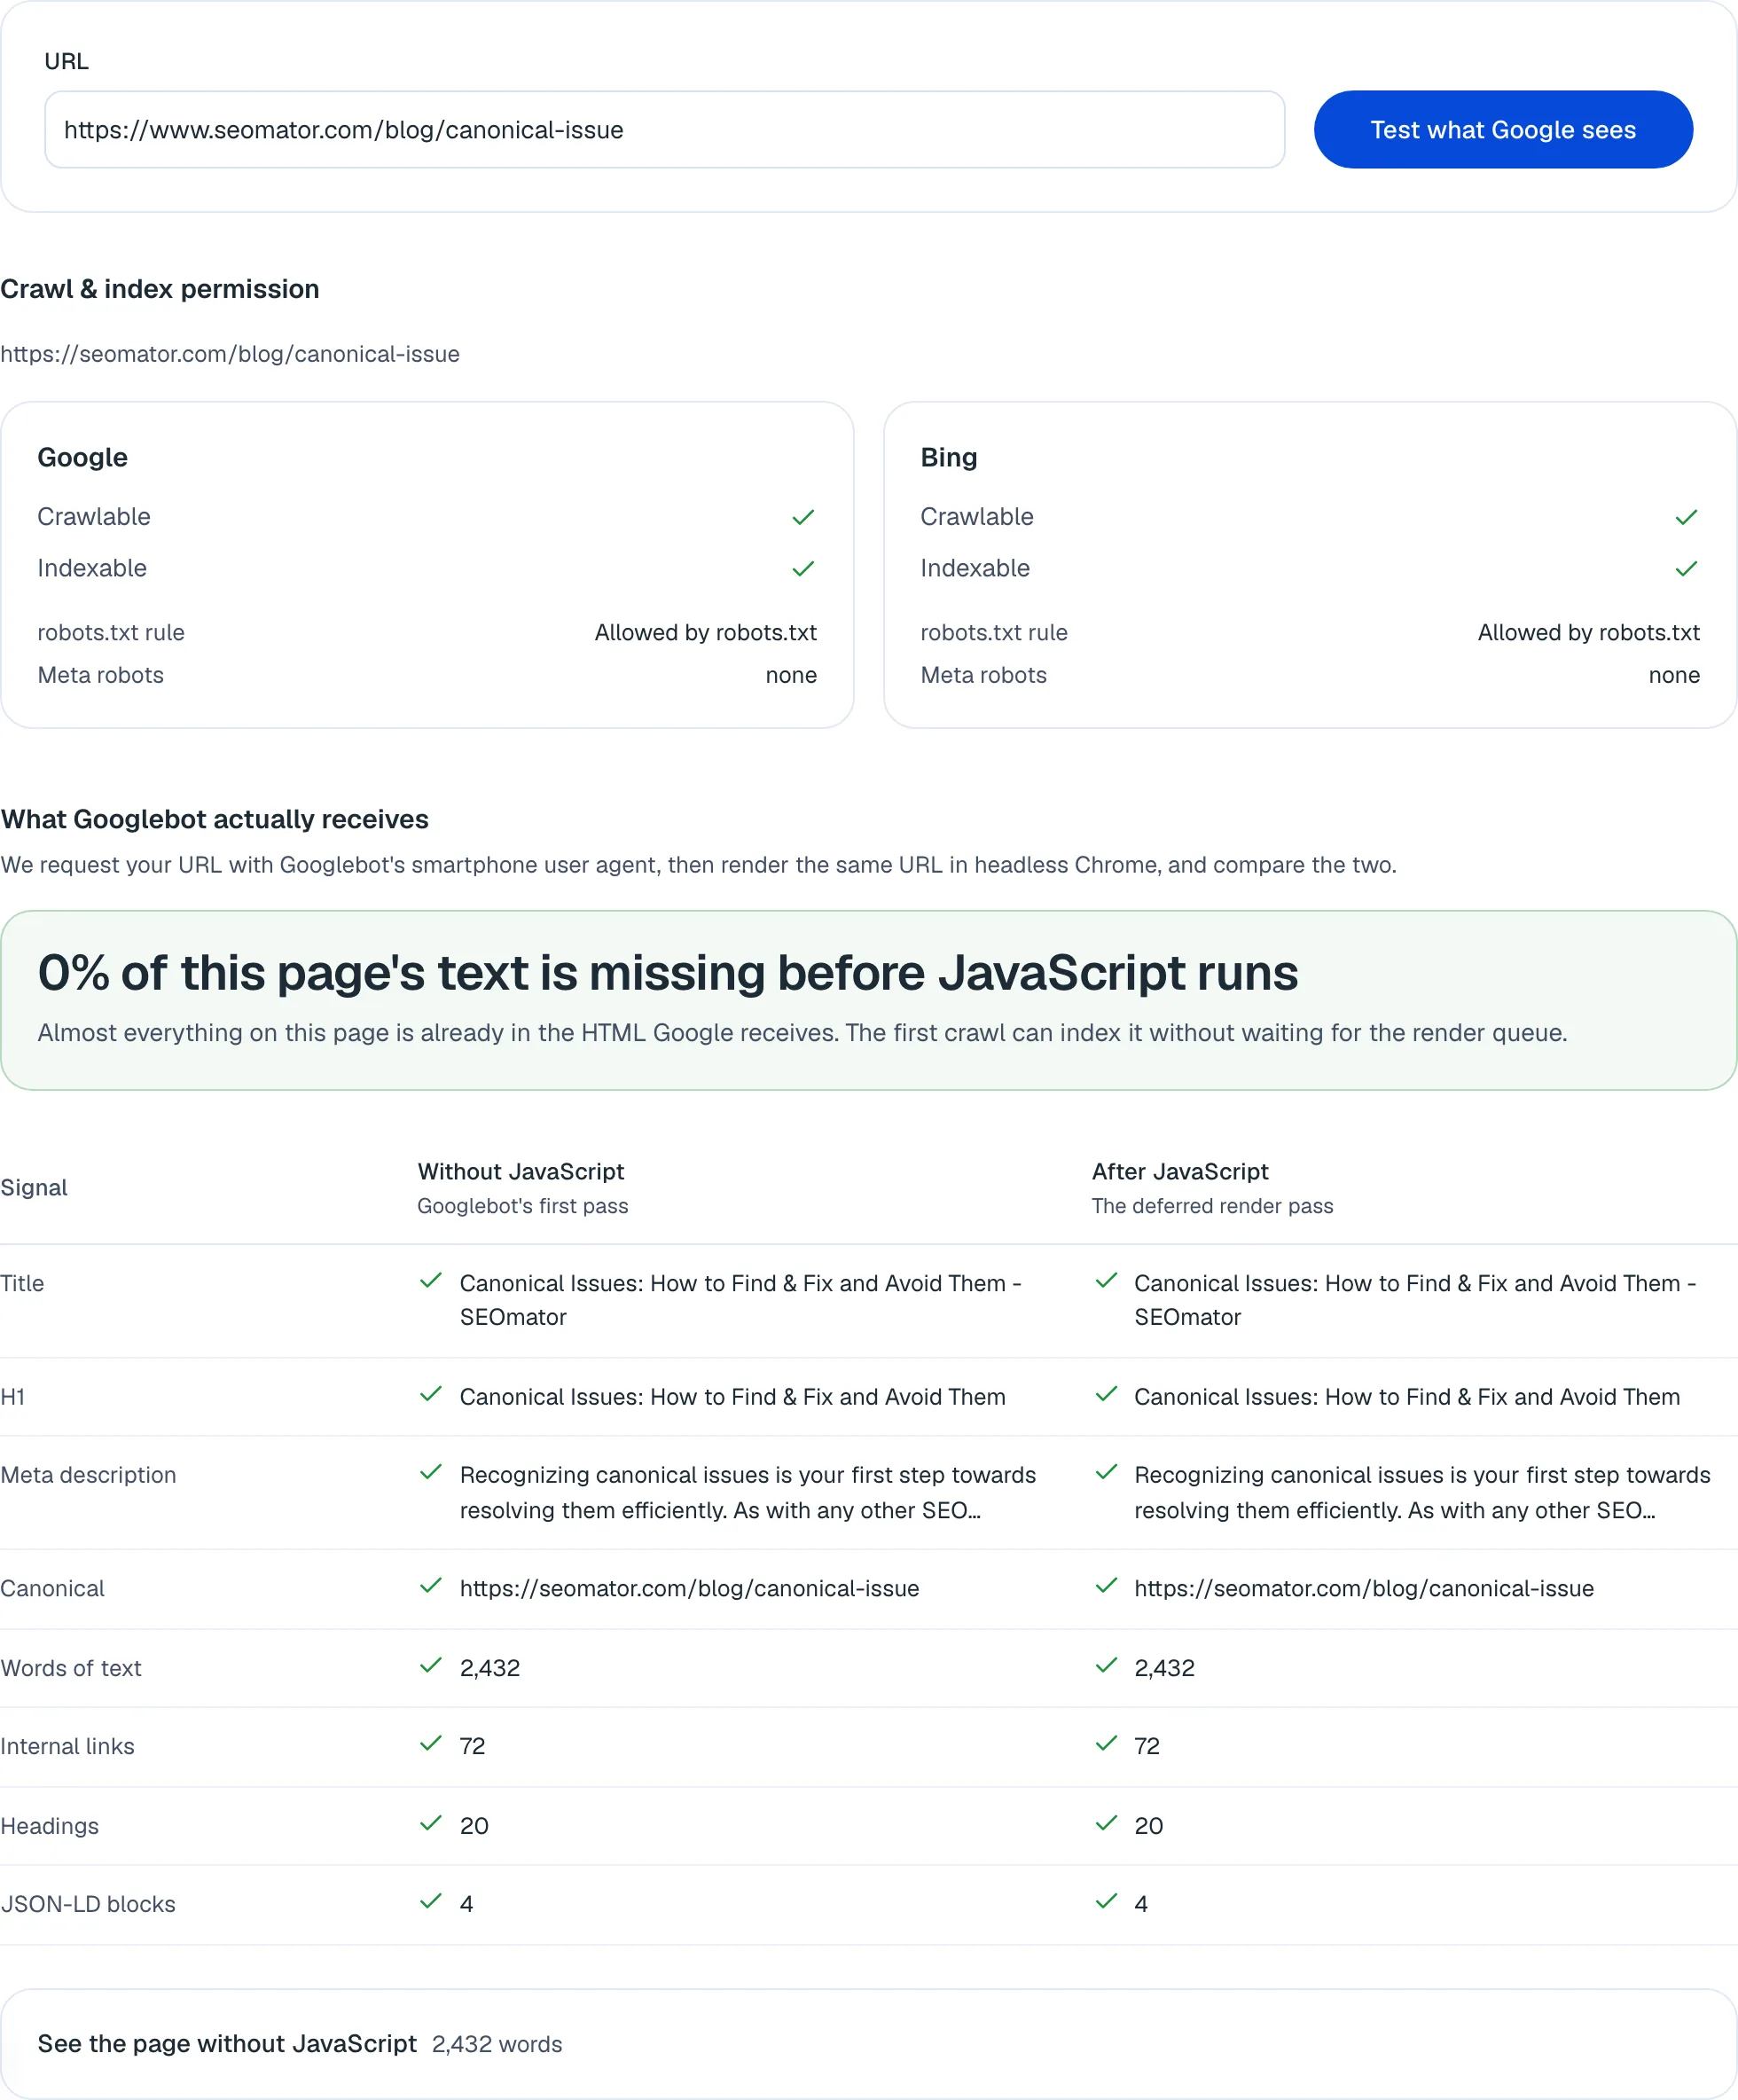
This free website crawl test answers two questions about any URL: whether robots.txt and meta robots let Google and Bing index it, and how much of the page exists before JavaScript runs. We fetch it as Googlebot, render it in headless Chrome, and show you the difference. No signup.
 Reviewed by Charles Duncan, Co-founder & CTO
Two checks run in parallel on every URL. The first parses your robots.txt with Google's longest-match rule and reads the page's meta robots tag. The second fetches the page twice — once as raw HTML with Googlebot's smartphone user agent, once through headless Chrome so JavaScript actually executes — and counts the same signals in both copies using one tokenizer, so the gap you see is a real difference and not an artefact of measuring two ways.
No account, no site verification, no ownership proof. Paste a homepage, a product page, or a deep filtered category — the pages most likely to have a rendering problem are rarely the homepage.
First the raw HTML, requested with Googlebot's real smartphone user agent — mobile-first indexing means that is the agent whose view decides. Then the same URL through headless Chrome, with JavaScript enabled and the network allowed to settle.
Title, H1, meta description, canonical, word count, internal links, headings and JSON-LD blocks are counted in both. Whatever exists only in the second copy is the part of your page Google indexes late, or never.
Everything the test reports is free and needs no account. A free SEOmator account is what turns a single URL check into ongoing monitoring.
Separate crawlable/indexable verdicts per engine, each with the robots.txt rule that decided it and the page's meta robots value.
The raw request carries Googlebot's real smartphone user agent, so you see the mobile-first view. If your server refuses that agent, the test says so — that alone explains some indexing failures.
One headline number: the share of your page's text that does not exist until JavaScript runs, measured against a full headless-Chrome render.
Read the actual text your server returned. If that panel is empty, an empty page is what Google's first pass has to work with.
Links that only appear after hydration are crawl paths Googlebot may never follow. Both counts are shown, because a discovery problem is worse than a content problem.
JSON-LD injected by JavaScript is only read on the deferred render pass. The test reports whether yours is in the HTML or arrives later.
Keep every test and watch the raw-vs-rendered gap move across deploys instead of checking it from memory.
Get told when a release pushes content out of the server HTML — the failure mode nobody notices until traffic drops weeks later.
This page tests one URL. An account crawls the full site and reports rendering, indexability and 250+ other checks across every page.
Monitoring, history and full-site crawls come with a free account.
Create a free account Reviewed byCharles Duncan · Co-founder & CTO
I built this because "can Googlebot reach the URL?" was never the interesting question — permission is trivial to check and is rarely the actual problem. The interesting question is how much of the page exists before JavaScript runs, and that number tends to surprise people: raw-vs-rendered content mismatch is the eighth most common failure our audit engine logs across the sites we crawl. The honest limitation is that our headless Chrome is not Google's renderer. We wait for the network to go quiet and take a snapshot; Google's Web Rendering Service has its own timeouts, its own resource budget and a queue nobody outside Google can see. Read a large gap here as a strong signal to investigate, not as proof that a specific page is unindexed — Search Console's URL Inspection is still the only tool that reports what Google actually stored.
 Charles Duncan · Co-founder & CTO
Across the 100K+ sites our audit engine has crawled in 2026, content present in the rendered DOM but absent from the raw HTML is the eighth most common failure we log — it appears on 31.4% of audited sites (H1 2026). It is not a niche single-page-app problem. It regularly turns up on sites whose teams are confident they are server-rendered.
The homepage is usually the one route a team remembers to pre-render. Paginated listings, filtered categories and search-result pages are where rendering quietly falls back to the client — and they are also where most of a site's indexable URLs live.
Zero internal links in the raw HTML is more serious than thin raw text. Text that arrives late gets indexed late; links that arrive late may mean the pages behind them are never discovered at all.
Google says it processes canonical links after rendering, but in practice a canonical that only exists post-render is one of the most common causes of the wrong URL being indexed. Put it in the server HTML and the ambiguity disappears.
If the initial response carries noindex, that is obeyed on the first pass. Removing it with JavaScript afterwards does not undo it, because the decision was already made before the render queue was ever reached.
Rendering strategy is not a property of your framework, it is a property of your current configuration. Major-version upgrades, a new edge-caching rule, or a component switched from server to client are all one-line changes that can move a page from server-rendered to JavaScript-dependent.
Most crawl checkers answer one question: is this URL allowed to be indexed? That is a permission question, and it is answered by two small pieces of text — a rule in your robots.txt and a meta robots tag in your HTML. It is worth checking, it takes milliseconds, and it is almost never the reason a page is missing from Google.
The second question is harder and far more often the culprit: what does Googlebot actually receive when it requests your URL?
Those are different failures with different fixes. A page can be perfectly permitted and still be indexed as a near-empty document, because the content a visitor sees was assembled in their browser by JavaScript that Googlebot's first request never ran. This test runs both checks side by side:
robots.txt is parsed with Google's longest-match rule, and the page's meta robots value is read, producing separate crawlable/indexable verdicts for Google and Bing.Everything below is about the second half, because that is the half people rarely have a way to see.
Google does not crawl and render in one step. It runs two passes, separated by an unknown amount of time.
Pass one — crawl and index the HTML. Googlebot requests your URL and receives whatever your server sends. It parses that response, extracts the text, headings, links, meta tags and structured data it finds in that response, and indexes them. It also queues every link it found for crawling. This pass is fast and it is the one that always happens.
Pass two — render. The page is handed to a separate service that loads it in a headless browser, executes JavaScript, and produces a rendered DOM. Google then re-indexes the page from that DOM. This pass is deferred: it sits in a queue, it has its own timeouts and resource budget, and it is prioritised like any other finite resource.
For most pages on most sites the second pass arrives. But three things follow from the architecture, and they are what make raw HTML matter:
This is why "Google renders JavaScript" is true and still not a reason to relax. Rendering is a second chance, not the first one.
The comparison table has one row per signal and one column per pass. The left column is what pass one receives; the right is what exists after JavaScript. Here is what each row is telling you.
Title, meta description, canonical. These belong in the server HTML without exception. A title set by JavaScript may be missed on the first pass, and a canonical that only exists post-render is a well-known cause of the wrong URL being indexed. If any of these three are present on the right and missing on the left, fix that before anything else — they are usually a one-line change.
H1 and headings. A missing H1 in the raw HTML alongside a present one after JavaScript is the classic single-page-app signature. It means your document arrives with no stated topic.
Words of text. The headline percentage on this page is computed from this row: how much of the rendered page's text is absent from the raw HTML. Small gaps are normal and not worth acting on — a cookie banner, a lazily-loaded testimonial, a chat widget. Large gaps mean the page's substance is not in the response Google indexes first.
Internal links. Treat this as the most important row after the meta tags. Text that arrives late is indexed late. Links that arrive late may mean the pages behind them are never discovered at all. Zero internal links in the raw HTML on a page that has dozens after rendering is a site-architecture problem wearing a rendering costume.
JSON-LD blocks. Structured data injected by JavaScript is read on the render pass, if the render pass arrives. Rich-result eligibility that depends on it is eligibility you are gambling on.
Below the table, the text preview prints the actual visible text extracted from your server's response. This is the least abstract output on the page: it is, literally, the version of your page Google indexes first. If it is empty, that is the finding.
Across the 100,000+ sites our audit engine has crawled in 2026, content that is present in the rendered DOM but absent from the raw HTML is the eighth most common failure we log — it appears on 31.4% of audited sites (H1 2026). It sits in the same tier as missing alt text and duplicate title tags: not exotic, not confined to experimental stacks, and frequently present on sites whose teams are confident they render on the server.
Five patterns account for most of what we see.
Teams pre-render the homepage because it is the page they demo, the page they test, and the page every tool defaults to. Paginated listings, filtered categories, search results and account-adjacent pages fall back to client rendering — and those routes are where the majority of a site's indexable URLs live. Always test a deep page.
Menus and pagination built from click handlers and router.push() produce no href for Googlebot to follow in pass one. The pages are reachable for humans and invisible to the first crawl. The fix is unglamorous: real <a href> elements, with the JavaScript enhancing them rather than replacing them.
Rendering behaviour is a property of configuration, not of your framework. A major-version upgrade, a component moved from server to client, or a new edge-caching rule can move a route from server-rendered to client-only without any visible change in a browser. Nobody notices, because the page still looks correct to everyone who looks at it.
A page that renders correctly after twelve seconds of API calls is a page whose render can time out. Google's renderer, like ours, gives up eventually. Slow rendering is a rendering failure with a delay attached.
Some servers refuse requests carrying Googlebot's user agent — usually as bot filtering nobody remembered was enabled. If this test reports that the Googlebot user agent was refused, that is worth immediate investigation: the real Googlebot verifies itself by reverse DNS, but a blanket block on the user-agent string catches it too.
In order of impact:
<a href="/products/widget"> in the HTML, whatever the click behaviour does on top of it.noindex decisions in the server response, and mean them. A noindex in the raw HTML is obeyed on the first pass. Removing it with JavaScript afterwards does not undo it — the decision was made before the render queue was reached.Fixing the raw HTML is more durable than trying to make the render pass faster, because it removes the dependency rather than racing it.
Three honest limits are worth stating.
Our renderer is not Google's. This test uses headless Chrome and waits for the network to go quiet before taking its snapshot. Google's Web Rendering Service has its own timeouts, its own resource budget, and a queue nobody outside Google can observe. A large gap here is strong evidence that a page is at risk; it is not proof that a specific URL is unindexed.
It cannot tell you what Google actually stored. Only Search Console's URL Inspection tool can do that, and only for properties you have verified. If this test shows a large gap and Search Console reports the page as indexed with full content, the render pass reached it — you were lucky rather than safe, but the page is fine today.
It tests one URL. A single result generalises to templates, not to a whole site. If a product page fails, assume every product page fails; but confirm it with a full site audit rather than assuming.
For the neighbouring checks, the robots.txt tester explains a blocked verdict in detail, the sitemap finder shows what you are actually submitting for crawling, and the mobile-friendly test covers the other half of mobile-first indexing. If Search Console is already showing the symptom, Crawled — currently not indexed is the report that most often traces back to what this test measures.
You moved a route to a client component and want to know, before it reaches production, whether the copy and links still exist in the server response.
Pages are indexed but ranking for nothing, or Search Console reports "Crawled — currently not indexed". Checking what the HTML actually contains takes ten seconds and rules the biggest cause in or out.
You need a concrete, demonstrable finding for a pitch — "84% of your product page doesn't exist until JavaScript runs" is a better opener than a generic site-health score.
Every result on this page — both verdicts, the full diff, the text preview — is free and requires no account, no email and no site verification.
Permission and reality are different failures with different fixes. Most tools answer one; this answers both from a single URL.
The comparison runs your page through headless Chrome. It is not inferred from framework fingerprints or a text-to-HTML ratio, which is how most "JS SEO checkers" guess.
The raw fetch identifies as Googlebot smartphone, because that is the crawler whose view of your site decides indexing. A desktop-browser fetch can return materially different HTML.
The no-JavaScript preview prints the actual extracted text. You can read the version of your page Google indexes rather than trusting a number about it.
Pair it with the robots.txt tester, the sitemap finder and the free site audit to take a single-URL finding and check it across the whole site.
Fetch as Google was a Search Console feature that showed how Googlebot retrieved and rendered a page. Google retired it in 2019 and folded its capabilities into the URL Inspection tool, which requires verified ownership of the property. This page is the free public equivalent for the part most people needed: it requests your URL with Googlebot's user agent, renders the same URL in headless Chrome, and shows you the difference between the two — for any URL, without verification.
Yes, but not immediately and not unconditionally. Googlebot crawls the raw HTML first and indexes what it finds there. Rendering happens on a second pass, handled by a separate service with its own queue, timeouts and resource budget. For most pages that second pass arrives, but it can be hours or days later, and pages that are slow, error-prone or low-priority can be indexed on their raw HTML alone. Content that exists only after JavaScript is therefore best treated as content that might get indexed, rather than content that will.
Because your browser runs JavaScript and the first column of this test does not. If the raw HTML column shows a handful of words while the rendered column shows the full page, your server is sending a shell and the browser is assembling the content. That is normal for client-rendered applications and invisible in day-to-day use — which is exactly why it goes unnoticed until pages stop being indexed.
No — the framework is not the problem, the rendering configuration is. React, Vue, Angular and Svelte can all produce fully server-rendered HTML, and all of them can be configured to ship an empty shell instead. The same repository can serve one route server-rendered and the next one client-only. That is why it is worth testing specific URLs rather than reasoning from your stack.
In order of impact: move the page's primary content, H1, meta tags and canonical into the server response (server-side rendering, static generation or prerendering, depending on your framework); make sure internal links are real anchor elements with href attributes in the HTML rather than click handlers; and keep structured data server-side. Fixing the raw HTML is more durable than trying to make the render pass faster, because it removes the dependency instead of racing it.
Website crawling is the process by which search engines discover and index new web pages. It is done by automated programs called "spiders" or "bots" that follow links on web pages to discover new pages, and then read their content to understand their context.
Search engines use automated programs called "spiders" or "bots" to crawl websites. These crawlers follow links on web pages to find new pages, and then they read the content of those pages to understand their content and context. They also record information about each page, such as the last time it was updated, how important the page is, and any other metadata that might be useful for understanding the page's content or context.
The frequency of crawling can vary depending on a site's popularity, the number of links pointing to it, and how frequently its content is updated. High-traffic sites or sites with frequently updated content may be crawled more often than low-traffic sites. However, it's important to note that there is no set schedule for when a site will be crawled.
Website owners can use robots.txt file and meta tags to control how search engines crawl their sites. The robots.txt file is a simple text file that can be placed in the root directory of a website, and it tells search engines which pages or sections of the site should not be crawled. Meta tags, such as the "noindex" tag, can also be used to control how search engines index and display a web page.
To get your website indexed by search engines, you can do the following: submit a sitemap to Google Search Console, include internal linking within the website, get external links from other websites, use structured data and schema markup, and make sure the website is mobile-friendly and has a fast page loading speed.
Crawling is the process by which search engines discover new web pages, and indexing is the process of adding those pages to a search engine's database. Crawling is the first step in the process, and indexing is the second step. Once a page is indexed, it is included in the search engine's database and can be returned in search results.
Deeper reading from the SEOmator blog on what this tool measures.
· 17 min read
We tested 390 top homepages: 36% of React or Vue sites without a meta-framework hid most of their text from AI crawlers. Here are 9 SPA SEO fixes.
· 16 min read
Only 45.9% of crawler requests return a 200. The 2026 crawl waste report breaks the waste down by client type, industry, and operator — and finds AI bots are the cleanest traffic on the web, not the dirtiest.
· 35 min read
I completed six AI SEO courses in the past year. Here's the order I'd take them in, who each one suits, and what they cost, from free to $319 a month.
Elevate your online presence with our tool: Get found, Get ahead


